

Descriptors Examination
-
On the Model Performance Grid, click View Log File.
A text editor window opens. The log file for the most recent model building run (the GA model) is displayed in the window.
-
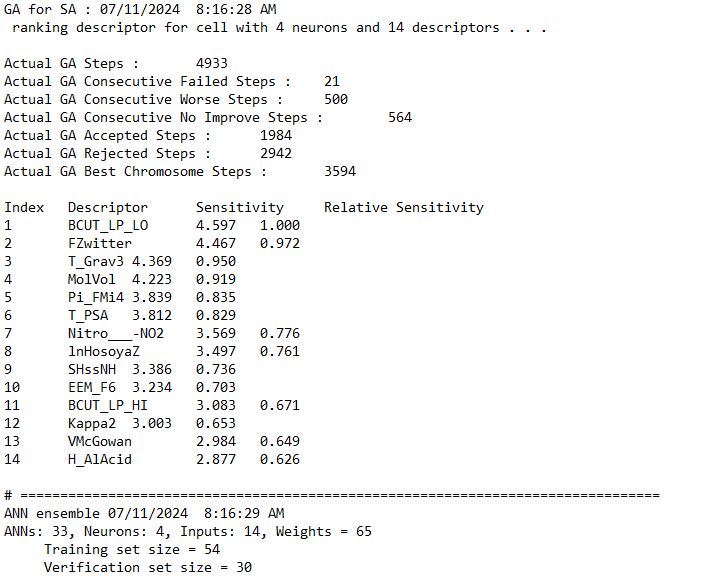
In the text editor window main menu, use an Editor command to search for a specific model by searching for Neurons: 4, Inputs: 14. The display advances to the entered text.
-
Do the following:
-
scroll the display up until the list of descriptors for this best model is visible in the window
-
increase the size of the window so that the model performance for this best model also appears in the display
-
Using the same text editor, navigate to the [\<AppData>]\Tutorial\Example 1 folder and open the folder that contains the Input Gradient (IG) model run from the tutorial "ANNE Regression Using Input Gradient for Descriptor Selection".
NOTE: If you followed the tutorial, this folder is namedExlogP_20xx-xx-xx_01.
-
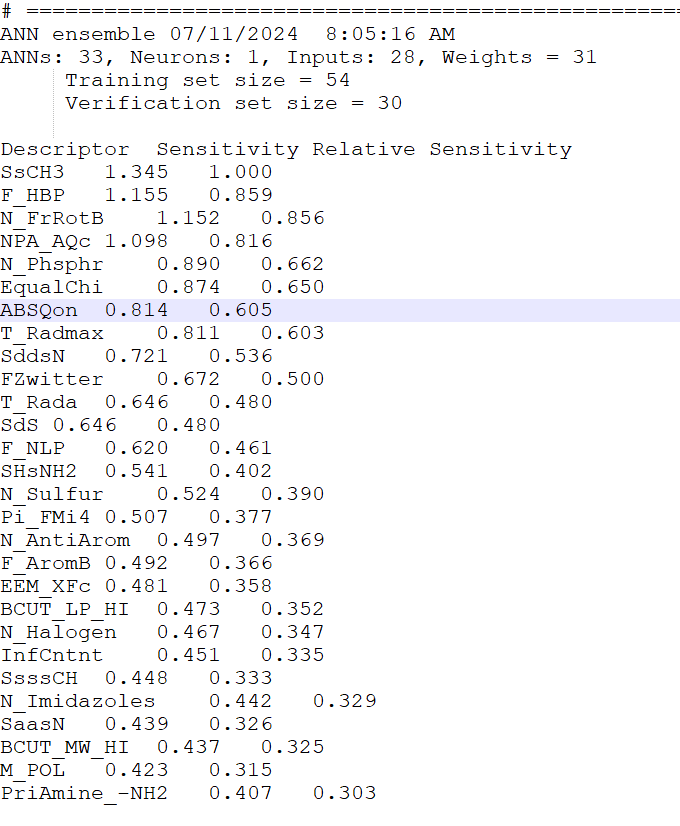
Open ExlogP_20xx-xx-xx_01.log file for the IG model run and scroll to the best IG model in that file (1 neurons and 28 descriptors), making sure that the full list of descriptors and the model performance is displayed in the window just as you did for the log file for the GA model run.
-
Compare the two log files for the IG and GA model runs.
The genetic algorithm calculates sensitivities for the selected descriptors based on their frequency in the population weighted by the cross-validation score for each individual chromosome model. Notice how only a few of the descriptors present in the GA descriptor list are present in the IG list. All descriptor sensitivity methods, with the exception of the Per Cell mode for the genetic algorithm, calculate and rank the sensitivity for all descriptors either once for the entire grid or once per row (neuron). This means that the descriptor with the highest sensitivity is the same for all models in the two neuron row. In contrast, when Per Cell is selected as the mode for the GA, the algorithm attempts to find the best descriptor combination and sensitivity ranking for the given number of inputs for each cell in the grid.
NOTE:
The GA Per Cell is the most computationally intensive method of all the descriptor selection methods. When used with large data sets, a representative subset of the training set is selected for the GA run to boost performance.